Spectral Attacks Reveal a Hidden Weak Spot in Vision-Language Models
Researchers found a way to attack vision-language models using the model's own internal geometry — aligning representations with the subspaces the model cares about least. It beats existing baselines, and the same insight could make these models tougher.
Automation needs a narrow first win
The best first AI workflow is usually a repeated task with a clear input, clear output, and a human approval step.
Here's a what-if that's now real: researchers have found a way to attack vision-language models by reading the geometry of the model itself — and it works better than the usual tricks. A new paper on arXiv introduces SSGRA, a white-box spectral-subspace-guided attack, and it opens a genuinely fresh window into why these models break at all.
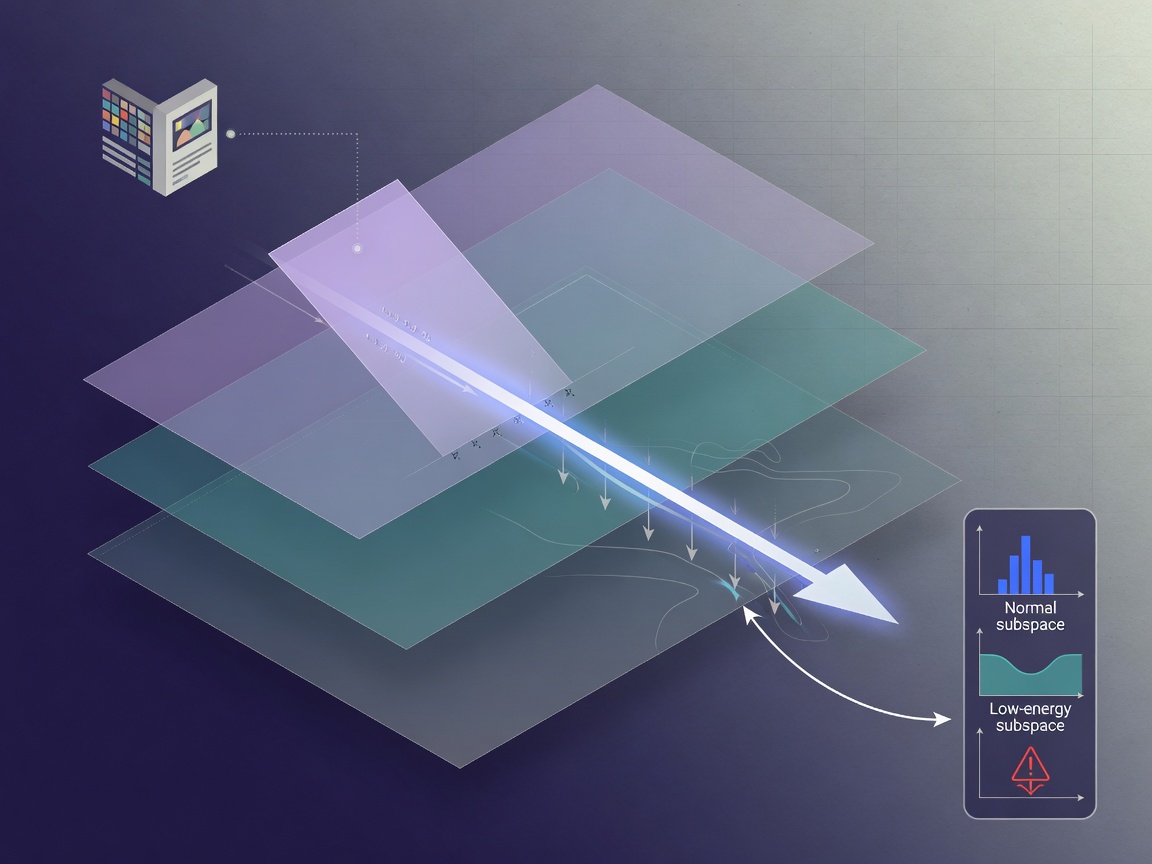
The core idea is deceptively elegant. Inside any transformer-based vision-language model, intermediate linear transformations are doing quiet, constant work — reshaping representations layer by layer. The researchers behind SSGRA zoom in on the spectral structure of those transformations, the singular-value anatomy that most adversarial research has largely ignored. Their attack aligns intermediate representations with the subspace spanned by the bottom right singular vectors — the directions the model itself treats as least important. Push representations into that low-energy space, and the paper demonstrates improved attack effectiveness over existing baselines.
Why Adversarial Attacks on Vision-Language Models Needed a New Angle
Most adversarial work hunts for input-level weaknesses: tweak the pixels, fool the classifier. SSGRA goes a level deeper and asks a structural question — what does the model's own internal math reveal about where it's fragile? The answer, per the source article, is that the spectral structure of intermediate linear transformations is an unexplored mechanism of adversarial vulnerability. That's a big deal, because it reframes vulnerability from a bug hunt into a geometry problem. The model's blind spots aren't just lurking in the data; they're written into how its layers transform information.
Worth a look
Phugialy Picks

AI Engineering: Building Applications with Foundation Models
A practical guide to building real-world applications with foundation models and LLMs.

GMKtec K15 AI Mini PC Oculink Intel Ultra 5 125U 32GB DDR5 512GB SSD | Desktop Computer AI Boost, 3X M.2 2280 Storage Expansion, Dual NIC...

Agentic AI Engineering: Systems That Reason and Act Autonomously – Designing, Building, and Prompting LLM-Based Agents for Real-World Deployment
Some Phugialy Picks use affiliate links. If you buy through one, Phugialy may earn a commission. It doesn't change what we recommend. Full disclosure →
What a Spectral Interpretation of Vulnerability Actually Unlocks
Here's the part I find genuinely exciting, and it's not the attack itself. The same spectral interpretation that makes SSGRA effective is, as the authors point out, a tool for improving robustness. If you can identify the subspaces where representations get dangerously aligned, you've got a diagnostic — a way to probe a model's weak geometry before someone else weaponizes it. Give this a year, and I'd expect spectral analysis to show up in the robustness toolkit the way attention visualization did: first as a curiosity, then as standard practice.
The real story here is that the attack and the defense are the same insight pointing in two directions. That's the pattern behind a lot of the best security research — the sharpest scalpel is also the best flashlight. For anyone building with vision-language models, this paper is worth reading not because white-box attacks are an everyday threat, but because it hands the community a new vocabulary for asking where a model's representations are quietly thin.
The bottom line: SSGRA demonstrates that the bottom of the singular spectrum matters, and that demonstration cuts both ways — a better attack today, and a plausible roadmap for sturdier models tomorrow. That's the kind of trade worth paying attention to.
Got a question about how this applies to you? →
Keep reading
Follow the thread
Polycepta Rethinks Multi-Object Tracking With Recursive Appearance
Polycepta stops matching appearances frame by frame and instead builds a continuously updated state for every tracked object — hitting 92.27% MOTA on KITTI at real-time speed. The interesting question isn't the benchmark number; it's whether recursive estimation holds up when occlusions get ugly.
Read this noteSame lane, different angle
Soft Robot Policy Learning Just Got Up To 40x Faster
A 40x speedup in simulation training sounds like a lab curiosity until you price what simulation time actually costs. New research on soft robot policy learning reports that switching to implicit time-stepping cuts train
FSU-QA Tests Foresight Intelligence in Vision-Language Models
Small Vision-Language Models fine-tuned on FSU-QA beat much larger frontier models at anticipating future events - but only when measured by FSU-QA itself. That circularity is the part worth thinking about before citing this result.