Your Playlists Are a Privacy Leak: Inferring PII From Spotify
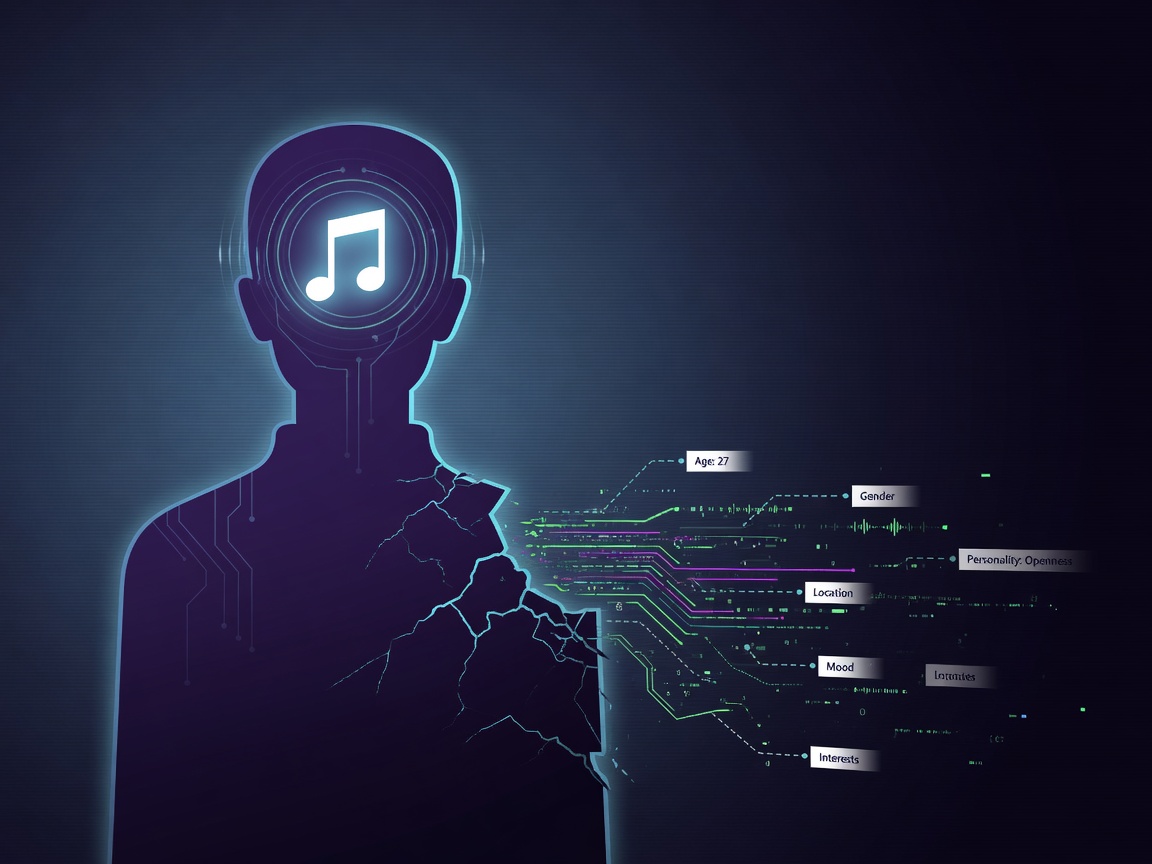
Researchers have built a deep learning tool that infers sensitive personal information — age, gender, country, drinking and smoking habits, even Big Five personality scores — from nothing but a user's public Spotify play
Automation needs a narrow first win
The best first AI workflow is usually a repeated task with a clear input, clear output, and a human approval step.
Researchers have built a deep learning tool that infers sensitive personal information — age, gender, country, drinking and smoking habits, even Big Five personality scores — from nothing but a user's public Spotify playlists. What the headline version of this skips is how unevenly that capability actually performs, and how modest the proposed defense turns out to be.
What The Tool Actually Claims To Do
The system, called musicPIIrate, is presented by its researchers as an example of "Offensive AI" — AI repurposed for malicious ends across the cyber-kill chain. It processes unordered, variable-length collections of public playlists using architectures designed for set- and graph-structured data: Deep Sets with pooling to handle the collection as an unordered whole, and Graph Neural Networks to model relationships between playlists. The claim is that a user's playlist collection isn't just a list of songs but a connected structure whose interconnections carry PII-carrying behavioral signals.
This rests on a well-documented foundation. Musical preferences have repeatedly been shown to function as psychological markers: Openness correlates with complex genres like jazz and classical, Extraversion with energetic mainstream styles like pop and rock. Age and cultural background shape taste in predictable ways — younger listeners gravitate toward contemporary high-arousal genres. Earlier work on Last.fm logs, and later analyses of thousands of shared Spotify playlists, already established that listening behavior encodes demographics, lifestyle habits, and personality. musicPIIrate's contribution is architectural: it combines both set-based and graph-based perspectives on that same public data.
Worth a look
Phugialy Picks

AI Engineering: Building Applications with Foundation Models
A practical guide to building real-world applications with foundation models and LLMs.

GMKtec K15 AI Mini PC Oculink Intel Ultra 5 125U 32GB DDR5 512GB SSD | Desktop Computer AI Boost, 3X M.2 2280 Storage Expansion, Dual NIC...

AI: Understand the Revolution: From Basics and Buzzwords to Tech Giants, Governments, and Your Future
Some Phugialy Picks use affiliate links. If you buy through one, Phugialy may earn a commission. It doesn't change what we recommend. Full disclosure →
What The Numbers Actually Show
The evaluation reports state-of-the-art inference accuracy across a wide array of attributes — demographics (age, country, gender), habits (alcohol, smoking, sport), and OCEAN personality scores. But the baseline comparison tells a more measured story: musicPIIrate beats existing methods in 9 out of 15 attribute inference tasks. That means for six attributes — over a third of them — prior methods performed as well or better. "State-of-the-art" here is real but partial; it holds for most attributes tested, not all.
The paper also doesn't specify per-attribute accuracy figures in the material available here, which matters enormously for judging practical risk. An attack that infers country at high accuracy is a different threat than one that infers alcohol consumption at barely-above-chance levels — the first enables targeted scams or surveillance by proxy; the second mostly demonstrates that a signal exists. Without those breakdowns front and center, the aggregate framing does more work than it should.
Who Bears The Cost If This Holds Up
This gets framed as a research finding about attack feasibility, but the actual weight falls on users who made an ordinary privacy decision: sharing playlists publicly because they wanted to share music. Nobody reads their Spotify profile as a psychological dossier. Yet the research lineage here — from collaborative-filtering studies to personality-behavior connections built on private Spotify data — shows these signals are extractable with increasingly off-the-shelf methods.
The proposed defense, JamShield, works by injecting dummy playlists into a user's account to dilute the PII-carrying signal. It lowers inference F1-score by an average of 10%. That figure deserves scrutiny in both directions: it's meaningful as proof that dilution works at all, but a 10% average reduction is not protection — it's degradation. An adversary with moderate baseline accuracy still retains most of it after JamShield runs. And there's an implementation wrinkle worth naming: injecting dummy playlists into user accounts means either users opt into polluting their own libraries or someone else modifies their accounts — neither is friction-free.
The Narrower Claim Worth Keeping
The defensible version of this result is narrower than "AI can weaponize your playlists." It's this: public playlist collections are now demonstrably inferential surfaces for demographic and behavioral attributes; graph-structured modeling improves extraction for most attributes but not uniformly; and signal dilution via dummy data offers measurable but partial mitigation.
That narrower framing points somewhere uncomfortable. The burden currently lands on individual users to either obscure their own taste or accept exposure — while the platforms holding this data face no stated obligation here at all. If playlist-level PII inference keeps improving (and this paper suggests it will), dilution tools like JamShield are stopgaps; platform-level access controls are where the decision actually sits.
Got a question about how this applies to you? →
Keep reading
Follow the thread
TimEE: Time Series Classification With Zero Real Training Data
A time series is just a list of numbers measured over time - heartbeats, sensor readings, stock prices - and classifying one usually means training a new model from scratch for every single dataset. TimEE, a new 4.5M-par
Read this noteSame lane, different angle
The Shift Toward Open-Weight Models as the Standard AI Substrate
If the open ecosystem is the inevitable winner, why are we still wasting resources building proprietary moats that are destined to be bypassed by a more portable substrate?
The Quadratic Wall: Why Brute-Force AI is Hitting a Ceiling
Generative AI is hitting a wall of physical and economic reality. While the hype focuses on what models like ChatGPT and Claude can do, the engineering reality is a "brute-force" approach that is becoming fundamentally u