2 min read
Back to all posts

Decoupling Knowledge from Weights: Why Co-LMLM Matters for Production

The fundamental issue with current LLMs is where they store facts: in the weights. This creates a massive headache for production teams because 'unlearning' a specific piece of information is nearly impossible without ex
AI ResearchLLMsMachine LearningKnowledge Bases
Decoupling Knowledge from Weights: Why Co-LMLM Matters for Production
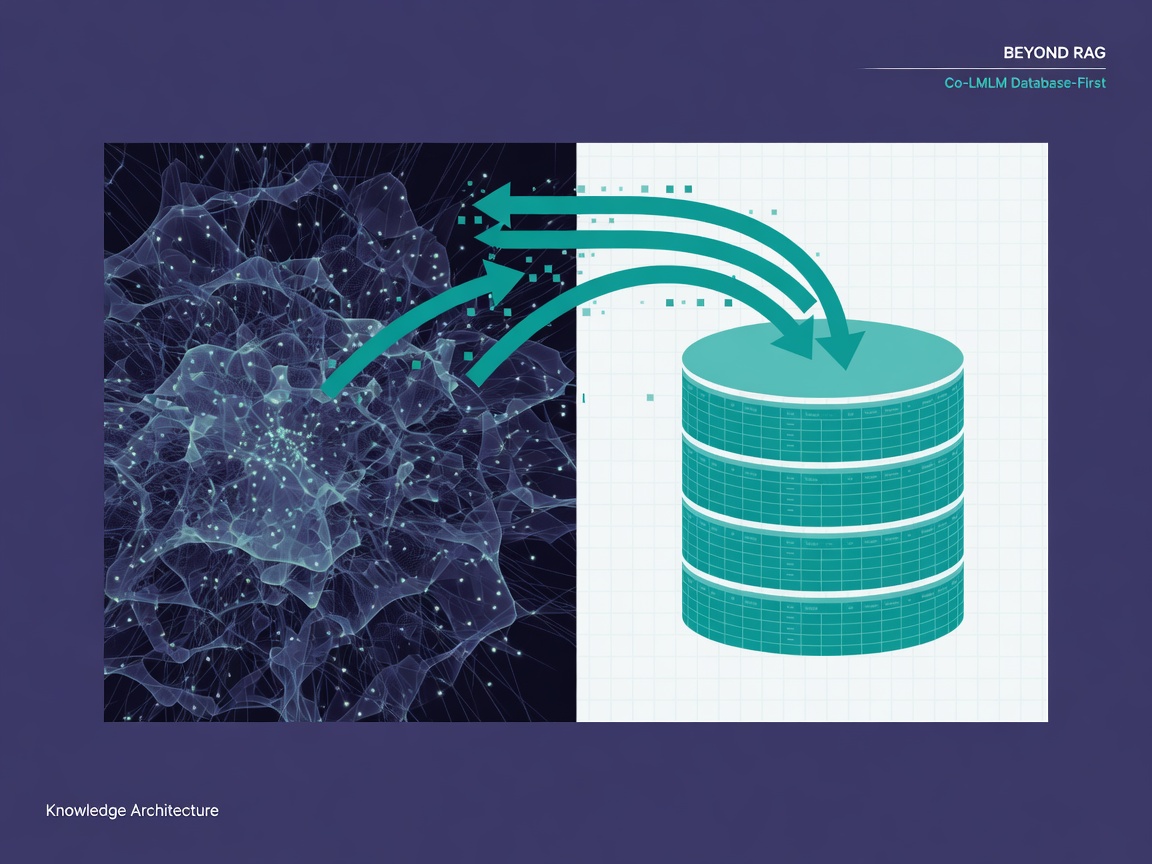
By tagging free form factual spans in arbitrary text, Co LMLM learns to identify and query facts from the messiness of real world data.
Reader Lens

Automation needs a narrow first win

The best first AI workflow is usually a repeated task with a clear input, clear output, and a human approval step.

The fundamental issue with current LLMs is where they store facts: in the weights. This creates a massive headache for production teams because 'unlearning' a specific piece of information is nearly impossible without expensive retraining, and ensuring 100% factual accuracy is a constant gamble. Cornell researchers are proposing a shift with Co-LMLM (Continuous-Query Limited-Memory Language Models), which externalizes factual knowledge into a dedicated knowledge base (KB). Instead of the model 'knowing' a fact, it queries a database during generation.

Moving Beyond Rigid Relational Schemas

Previous attempts at limited-memory models usually relied on structured relational tuples. This forced developers to map facts into rigid, database-like schemas, which is a bottleneck for scale. Co-LMLM replaces this with continuous vector queries. This is a critical technical distinction; it allows the model to handle much broader, more fluid knowledge types by mapping semantic similarity rather than just strict keyword matches. This is where most standard retrieval-augmented generation (RAG) systems struggle with nuance.

Furthermore, the training pipeline moves past the 'Wikipedia-only' bias seen in earlier work. By tagging free-form factual spans in arbitrary text, Co-LMLM learns to identify and query facts from the messiness of real-world data. It’s learning to navigate the noise, not just a curated encyclopedia.

Worth a look

Phugialy Picks

The Agentic AI Bible: The Complete and Up-to-Date Guide to Design, Develop, and Scale Goal-Driven, LLM-Powered Agents that Think, Execute...
Amazon

The Agentic AI Bible: The Complete and Up-to-Date Guide to Design, Develop, and Scale Goal-Driven, LLM-Powered Agents that Think, Execute...

OMOTON C2 Adjustable Aluminum Phone Stand
Amazon

OMOTON C2 Adjustable Aluminum Phone Stand

We'd buy this if: You want your phone upright on your desk for calls/notifications without a cable getting in the way.

We'd skip this if: You never keep your phone on your desk.

Screen Mom Screen Cleaner Spray (16oz)
Amazon

Screen Mom Screen Cleaner Spray (16oz)

We'd buy this if: You've been wiping your monitor with your shirt sleeve.

We'd skip this if: You already have a cleaning routine sorted.

Some Phugialy Picks use affiliate links. If you buy through one, Phugialy may earn a commission. It doesn't change what we recommend. Full disclosure →

The Trade-off Between Data Efficiency and Latency

The benchmarks are compelling. At a 360M parameter size, Co-LMLM achieves lower perplexity than models trained on 40x more data. On SimpleQA, it performs in line with gpt-4o-mini and beats Claude Sonnet 4.5. But for those of us actually shipping models, the real story is the decoupling of knowledge from parameters.

The model retains the controllability of LMLMs—specifically the ability to perform direct unlearning through database operations without the 'utility tradeoff' seen in fine-tuning. If you can delete a row in a database to 'unlearn' a fact, you solve a massive compliance and safety hurdle that weights alone cannot address.

However, we need to be realistic about production scale. While the paper claims 'minimal cost' for generating vector queries, the latency overhead of continuous retrieval in a high-throughput environment is a known variable. We’ve seen 'minimal cost' turn into 'unusable latency' once you move from a research paper to a production inference pipeline. The next hurdle isn't just the architecture; it's the engineering of retrieval speed.

Source and trust note

Built from source research and filtered through practical implementation judgment.

Reference: arxiv.org

Field Notes

Field Note· September 15, 2026

Memory Lanes: Why Your AI Agent Should Think Small Before It Thinks Big

To every developer out there — quick question. Why does an AI model sometimes answer you instantly, and other times pause like it's actually thinking about it? The answer is memory, and once you actually get how it works, you build agents that do less work and get smarter results — not the other way around. It's a genuinely wild time to be in this field. Coding used to be about fundamentals: sharpen your syntax, shave off milliseconds, beat the next person to the result. That still matters. But the AI boom cracked something open — now an agent can go head-to-head with a human, a bot, or another agent, and it doesn't really matter which. The competition itself is pushing us past syntax and scripts into questions like: how much can one agent actually hold in a single conversation? The big labs are racing at a scale most of us will never touch. So instead of trying to out-scale them, I think the rest of us should think small — per call, per token, per process. Nail that, and scaling later is the easy part. What memory actually means Simple: it's any information your AI system keeps around and reuses beyond the one exchange that produced it. Everything below is just a different flavor of that one idea. Every agent has its own way of handling that — some cached, some sitting on your device, some shipped off to a server. Why does any of that exist? A few real reasons stack up, not just one. There's the context window — limited space per call, so memory is partly how a system reaches past what fits in one conversation. There's cost — re-sending or re-computing the same thing over and over adds up, so caching saves real money. There's accuracy — pulling from real, current data instead of guessing keeps an agent grounded instead of making things up. And yes, personalization too. That last one's just the one you notice first as a user — it's not the whole reason this stuff exists. Six types of memory, quickly Short-term (working) memory — whatever's alive in the current chat. The second it ends and nothing got written down, it's gone. Long-term memory — meant to survive past this one chat. The model doesn't magically remember you tomorrow; something has to physically write it down and hand it back later. Persistent memory — long-term's tougher sibling. Less about "does it last," more about "does it survive getting knocked over" — restarts, crashes, redeploys. Stored somewhere solid, not somewhere that evaporates. Episodic memory — memory of one specific moment. "This person asked me X yesterday." Tied to an event, not a fact. Semantic memory — general knowledge, no event attached. "Python is a programming language" doesn't care who asked or when. Chunking — real talk, this one's not actually a type like the other five. It's the delivery method. You can't hand a model an entire book in one shot, so you slice it up first, store the pieces, and only pull back the couple that matter. No chunking, no realistic long-term memory — it's the plumbing everything above runs through. Now, back to that instant-vs-pauses question from the top. For the instant answer, the fact was baked into the model during training — closer to semantic memory than anything stored and fetched. For the pause, it didn't have that baked in, so it went and got it — actual retrieval. One wrinkle: sometimes a model pauses just to reason more carefully, even when it already knows the answer. Looks identical from the outside. Different thing entirely — that's reasoning time, not memory. (Quick aside for developers: if you're calling AI models through an API, look into OpenRouter. It gives you one API to call basically any AI model out there instead of wiring up each provider separately.) So here's the real question: when your agent goes and retrieves something, does it actually know what to do with it? Honest answer — it depends. Entirely on how you process it, and how you design around it. Think of any AI workflow as three steps: Trigger → Process → Output. The heart of it is Process — specifically when you call your data. Before the prompt? After it? Before the output? During validation? Every choice is a trade-off: more retrieval, more precision, more tokens burned. And that cost doesn't multiply per user — it multiplies per prompt. One user, a hundred prompts in a session. Keep that in mind. Why does any of this matter? Because being smart isn't about doing more work — it's about not doing too much work. Imagine calling up every book in a library to answer "what's 1+1" or "how do you spell A." The model probably already knows without any of that. If you're building something real for real users, you already know they won't accept "well, technically I checked every book first" as a good answer. (Somewhere there's probably an edge case that needs the deep search — not the point here.) I just want to plant the idea and let you sit with it. So how do I actually use this? On my own blog's pipeline: memory gets stored every time new data is discovered. It gets pulled back out before every write. After every validation, anything that came out wrong or out of place gets stored too — as a persistent memory — so the same mistake doesn't happen twice. Then a log gets written after every push. I'm not going to show you the whole system here. I'd rather you sit with the idea and build your own version of it — that's how this stuff actually gets better for everyone. Hope this helps you build whatever you're working on.

Got a question about how this applies to you? →

Keep reading

Follow the thread