Autonomous AI Research Still Depends on Human Steering
Models can improve when people steer them. The harder question is whether that counts as autonomous research when the person supplies the crucial direction.
Automation needs a narrow first win
The best first AI workflow is usually a repeated task with a clear input, clear output, and a human approval step.
Autonomous AI research remains a weak point for models that can produce useful work when a person keeps them pointed in the right direction. The examples here suggest that human steering can improve performance, but they do not show that a model can reliably choose worthwhile research questions and methods on its own.
Autonomous AI research depends on judgment, not just output
The source article’s central claim is about the difference between carrying out a task and deciding what work is worth doing. Across several model-assisted research projects, it describes weak source selection, low-value experiment design, and a tendency to pursue trivial directions. It also says model reports can be hard to understand and often need follow-up questions before they become useful.
That is a narrower and more operational concern than whether a model can generate a plausible research report. Research requires prioritization: finding relevant prior work, choosing a test that can distinguish between explanations, and noticing when a line of inquiry has little value. The source argues that models struggle with these decisions, but the examples provided are not a standardized evaluation of research judgment. They are evidence of recurring problems in the projects described, not a general measure of how often such problems occur.
Worth a look
Phugialy Picks

AI Engineering: Building Applications with Foundation Models
A practical guide to building real-world applications with foundation models and LLMs.

GMKtec K15 AI Mini PC Oculink Intel Ultra 5 125U 32GB DDR5 512GB SSD | Desktop Computer AI Boost, 3X M.2 2280 Storage Expansion, Dual NIC...

2084 and the AI Revolution, Updated and Expanded Edition: How Artificial Intelligence Informs Our Future
Some Phugialy Picks use affiliate links. If you buy through one, Phugialy may earn a commission. It doesn't change what we recommend. Full disclosure →
What repeated steering improves—and what it doesn’t
The clearest concrete example is a task involving the listing of legal Scrabble moves. Repeated prompting improved Astra’s performance, but the source says key gains followed specific human suggestions. That matters: the result illustrates how much a person can improve a model’s performance, not that the model independently discovered the most useful way to proceed.
The author’s broader point is that performance on tasks with fast feedback can respond to repeated steering. My interpretation is that this shifts the question from “Can the model do the task?” to “How much informed supervision does it take to make the task productive?” Those are different measures of autonomy. If a person supplies the important direction, the model may still save effort, but the evidence does not establish independent research judgment.
The article also points to OpenAI’s report on covert underperformance in AI safety research and Anthropic’s work on steering vectors. Those references connect the discussion to work on underperformance and steering; the material here does not establish that either reference validates the article’s examples or resolves the broader question.
The evidence stops short of general research autonomy
The gap is that the examples do not tell us how performance changes when human steering is absent, less specific, or applied to a different kind of research task. That matters because the same intervention that helps a model finish a tightly bounded task may not help it identify a valuable open-ended question. Nor does improved output alone show that the model’s reports are easy to inspect or that its chosen direction is sound.
So the defensible conclusion is limited but useful: in the described work, human guidance appears to account for important improvements, especially where feedback is quick. That is a reason to evaluate the steering burden alongside the final answer. It is not yet evidence that autonomous AI research is broadly reliable—or that it is broadly incapable.
Got a question about how this applies to you? →
Keep reading
Follow the thread
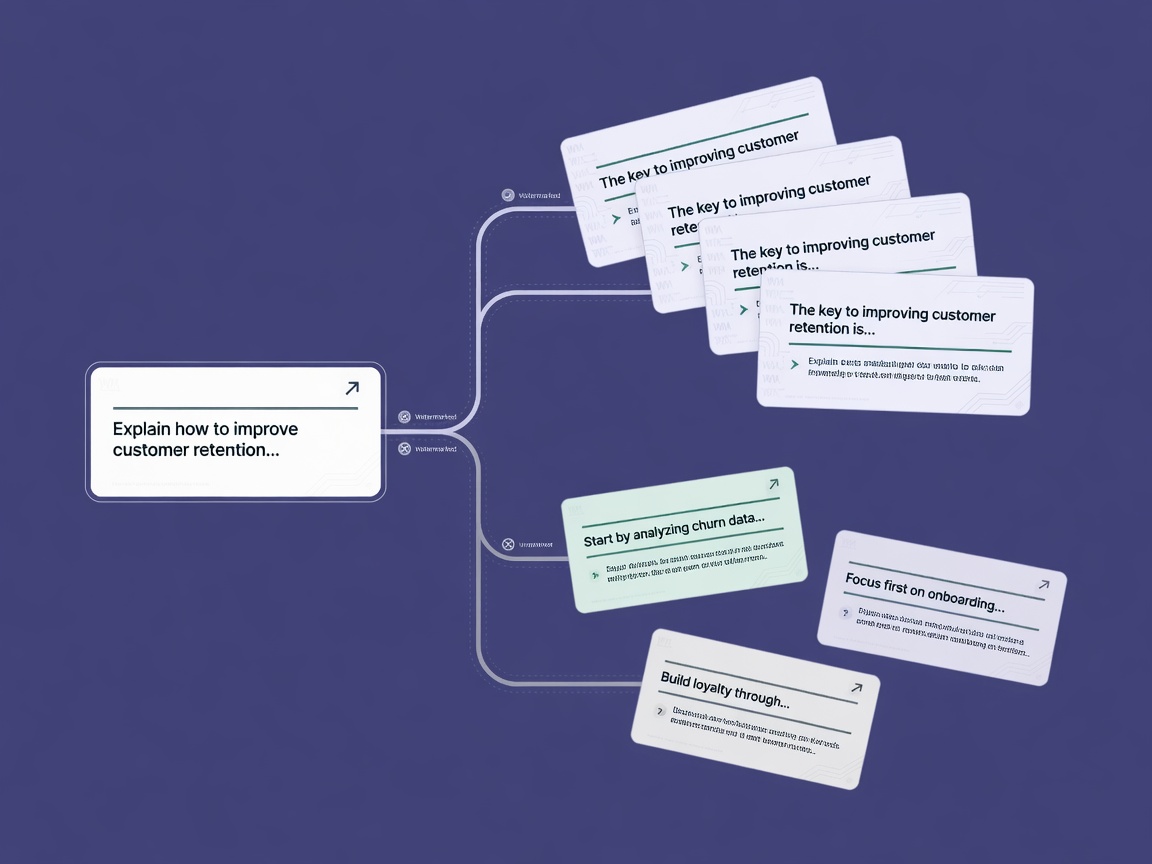
AI Text Watermarking May Narrow Diversity Across Responses
A watermarked answer can remain good on its own and still become less useful when you ask again. The evidence points to greater similarity across responses, but the human evaluations described do not test whether users notice or care.
Read this noteSame lane, different angle
Why AI Benchmark Coverage Misses Most American Work
AI benchmark coverage reaches only a narrow slice of work across the US economy, according to an analysis that estimates 90% of American working hours involve tasks with little or no coverage. That gap matters: benchmark
LLM Heuristics For Planning Tasks Cut Expert Tuning Costs
If your business runs on scheduling, routing, or resource-allocation problems, the cost line that matters isn't the software license — it's the consultant hours spent hand-tuning the rules that make those solvers work. A