In-Context Search: Why LLM Retry Loops Actually Work
Why does a language model sometimes get the right answer on its second try after failing on its first? A recent theoretical paper offers an answer: the model isn't just "trying again" - it's doing something that looks a
Automation needs a narrow first win
The best first AI workflow is usually a repeated task with a clear input, clear output, and a human approval step.
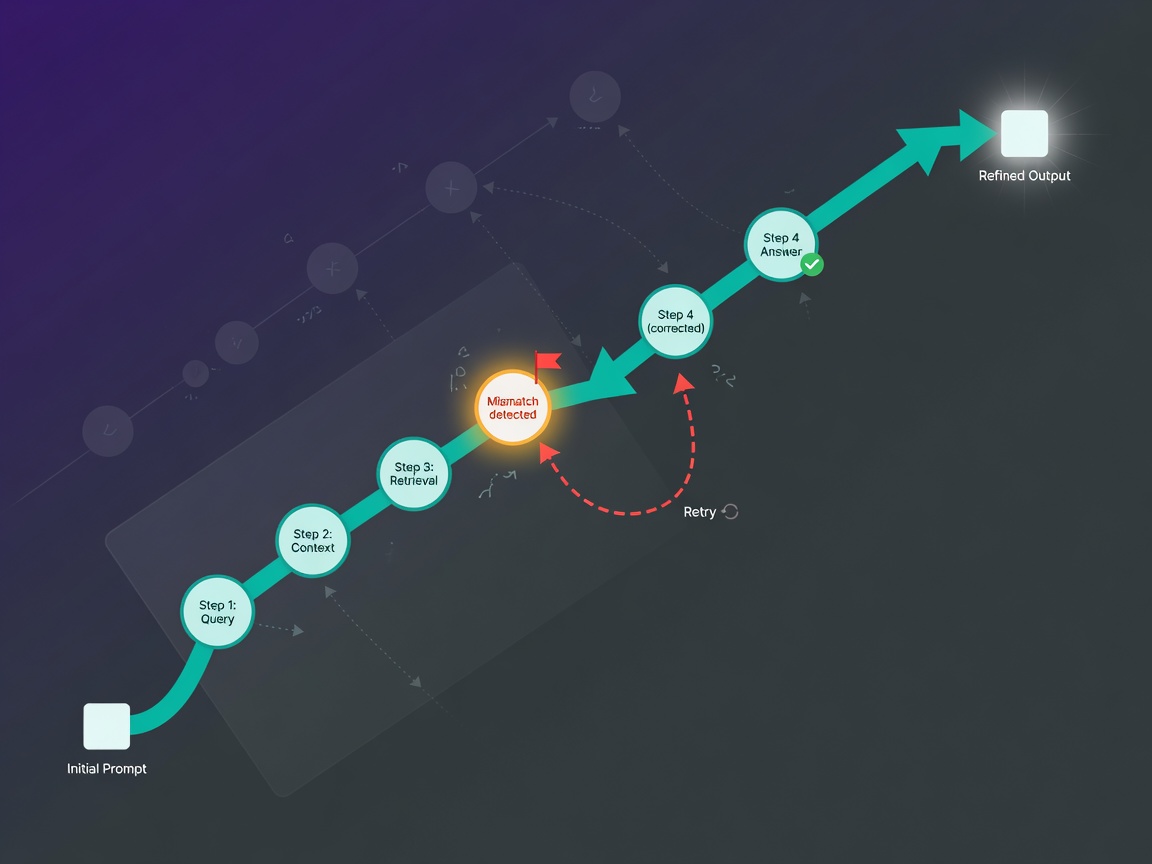
Why does a language model sometimes get the right answer on its second try after failing on its first? A recent theoretical paper offers an answer: the model isn't just "trying again" - it's doing something that looks a lot like search, and under the right conditions, that search pays off exponentially.
In-Context Search Is Really Approximate Inference
The paper models what it calls in-context search - the loop where a model generates a solution attempt, critiques it, and revises it within the same conversation - as approximate inference over reasoning traces. Here's what that means in plain terms: the model's first guess reflects its prior, its built-in beliefs about what a good answer looks like. Each round of self-reflection acts as feedback that updates those beliefs, the way evidence updates a posterior in Bayesian statistics.
The key insight is that this isn't magic or mere repetition. If the model's reflections reliably point at where things went wrong early in a reasoning trace, each revision is genuinely narrowing down the space of possible answers rather than rolling the dice again.
Worth a look
Phugialy Picks

AI Engineering: Building Applications with Foundation Models
A practical guide to building real-world applications with foundation models and LLMs.

GMKtec K15 AI Mini PC Oculink Intel Ultra 5 125U 32GB DDR5 512GB SSD | Desktop Computer AI Boost, 3X M.2 2280 Storage Expansion, Dual NIC...

AI: Understand the Revolution: From Basics and Buzzwords to Tech Giants, Governments, and Your Future
Some Phugialy Picks use affiliate links. If you buy through one, Phugialy may earn a commission. It doesn't change what we recommend. Full disclosure →
Why Exponential Improvement Only Needs Polynomial Effort
The paper's central result is the asymmetry between what you put in and what you get out. When reflections reliably localize early mistakes, in-context search yields exponential improvements over the base model - but it only needs a polynomial number of sequential attempts to get there. That gap between exponential gain and polynomial cost is the whole story.
The analysis also shows this behavior can be trained efficiently: cross-entropy training on search rollouts recovers the required behavior with polynomial sample complexity. And under reinforcement learning, the optimal policy ends up implementing the same posterior reweighting rule - meaning whether you train by imitation or by RL, you converge on essentially the same mechanism.
The Catch Is in One Word: Reliably
Most coverage of iterative refinement stops at "the model critiques itself and gets better." But everything hinges on that condition - reflections must reliably localize early mistakes. If self-critique flags the wrong error, or misses the real one buried three steps back, each revision isn't updating toward truth; it's drifting. The exponential guarantee doesn't apply to vague reflection, only to reflection that actually finds the fault.
That distinction matters because it reframes what we should be measuring. The real story here isn't "models can check their work" - it's that check quality is a multiplier on everything else. A base model with sharp self-diagnosis behaves like an exponentially stronger system; one with sloppy diagnosis behaves like itself with extra steps.
In my reading, this also connects to why some reasoning models feel inconsistent: their reflection loop is only as good as its ability to localize where reasoning actually broke, which is a much narrower skill than sounding reflective. It echoes a theme I keep returning to - surface-level review behavior and genuine error-finding are easy to conflate but very different things.
So when you see a model succeed on attempt five after failing attempts one through four, don't credit persistence. Credit accurate localization - that's the mechanism doing the heavy lifting.
Got a question about how this applies to you? →
Keep reading
Follow the thread
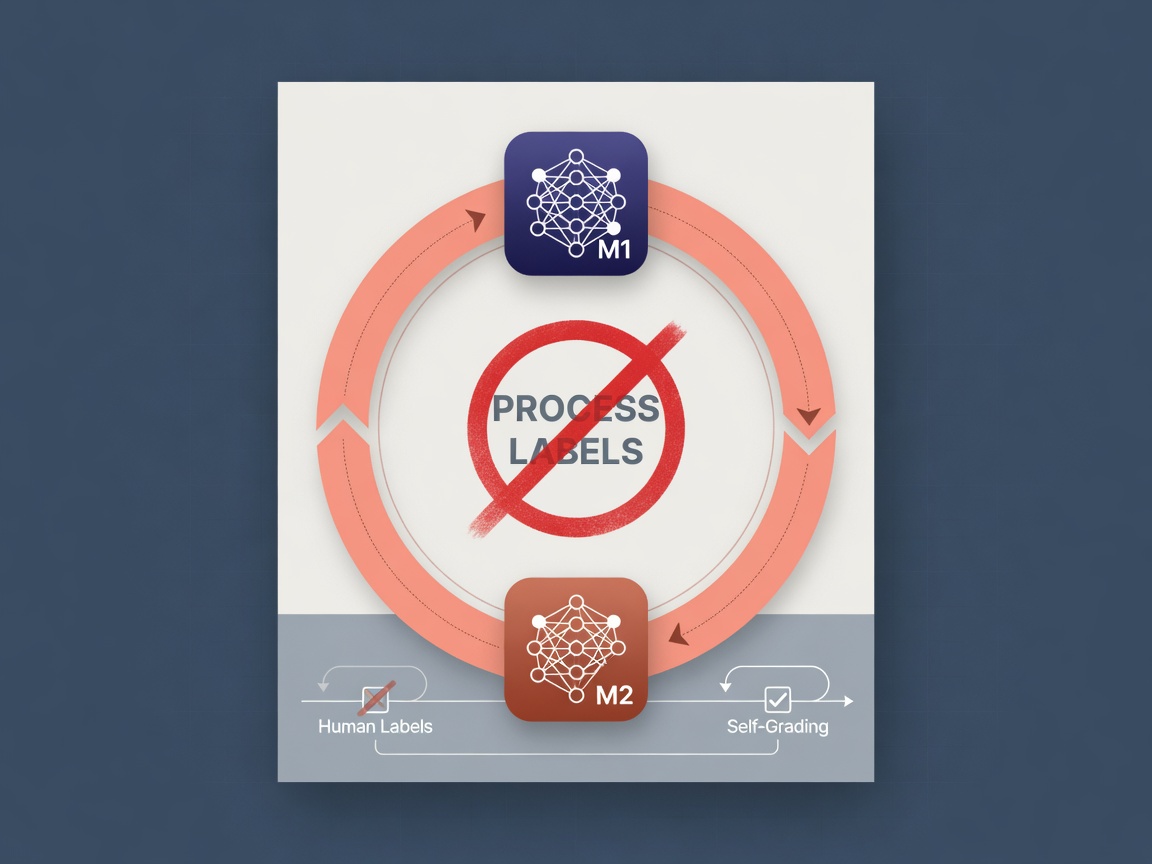
Agon: Two Models Grading Each Other Replace Process Labels
Two models grade each other's work and double GRPO's pass@1 on math and coding benchmarks — with zero process labels and no reward model. The catch shows up when you try to ship it.
Read this noteSame lane, different angle
The Geometry of Thought: Decoding the AI Black Box
Deep learning often feels like a series of miracles, but at its core, the "black box" of neural networks is actually a problem of geometry. While we know that deep feedforward ReLU networks (Multi-Layer Perceptrons or ML
AI Tutors Work Only If Students Use Them: Trial
A two-year trial across 18 middle schools found Khan Academy's AI tutor raised math scores modestly - but here's the catch: the gains looked just like those from practice without any AI at all. The real story isn't whether AI tutoring works; it's that 96% of students tried it and almost none used it when they actually needed help.