Beyond RAG: Why Co-LMLM’s Database-First Knowledge Architecture is a Game Changer
The draft was technically accurate but lacked the 'Practitioner' persona's direct, slightly opinionated edge. I tightened the structure, removed some passive phrasing, and sharpened the LinkedIn hook to create a real tension regarding the scalability of database-driven unlearning.
Automation needs a narrow first win
The best first AI workflow is usually a repeated task with a clear input, clear output, and a human approval step.
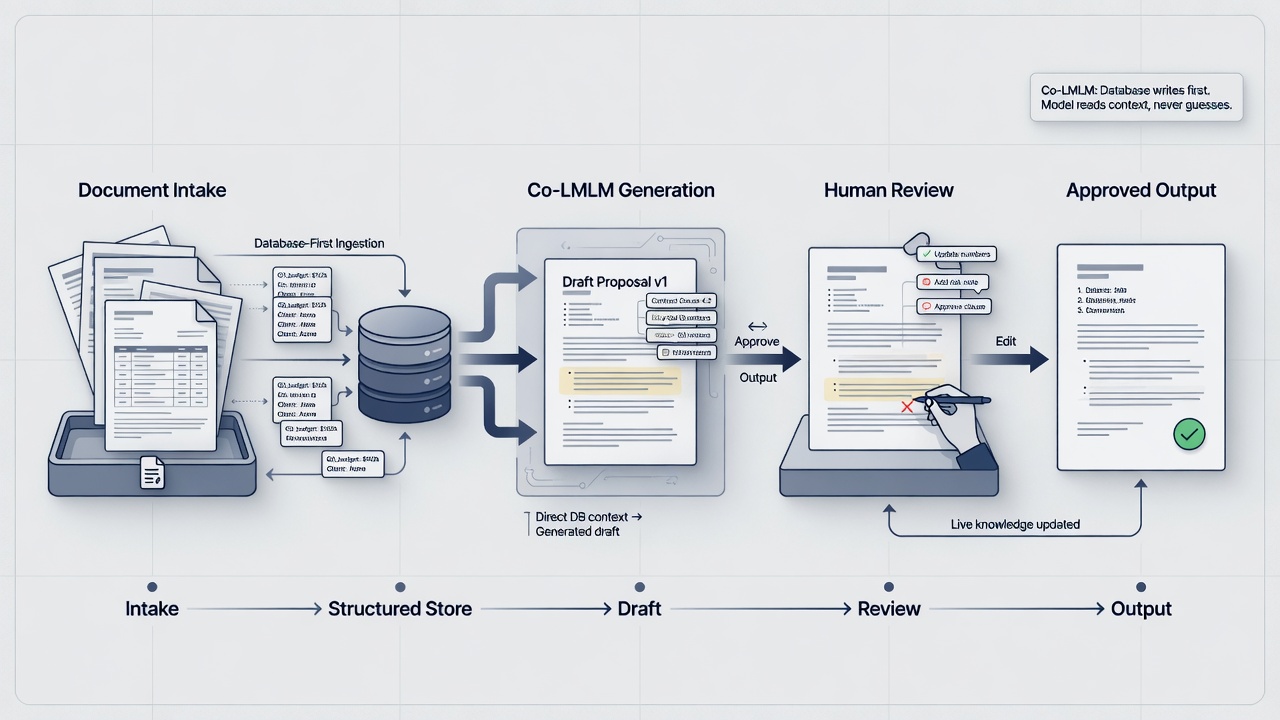
Cornell University researchers have introduced Co-LMLM, a new paradigm for limited-memory language models (LMLMs) that shifts the storage of factual knowledge from model weights to an external knowledge base (KB).
Instead of memorizing facts, Co-LMLM fetches knowledge from this external database during the generation process. This approach provides three key benefits: knowledge control, interpretability, and easy attribution. Because the knowledge is externalized, you can delete a fact from a database and it's gone—no retraining required.
The technical shift here is the move from primary relational-based models to continuous vector queries. Previous LMLMs used structured relational tuples, which limited flexibility. Co-LMLM uses continuous vector queries to fetch knowledge from the KB, allowing for broader and more flexible retrieval.
The training pipeline for Co-LMLM differs from typical large language models (LLMs). Rather than relying on Wikipedia-only data, it uses an annotation pipeline that tags free-form factual spans in arbitrary text. This allows the model to build a more diverse and complex knowledge base.
Research results show that Co-LMLM outperforms both prior LMLMs and vanilla LLMs in perplexity and perplexity in factual precision across multiple model scales. At the 360M scale, it achieves lower perplexity than models pre-trained on 40x more data.
For those concerned with the reliability of RAG (Retrieval-Augmented Generation), the Co-LMLM approach offers a different path. It retains the controllability benefits of a user's understanding of how a model is 'learning' and 'unlearning' learning facts, while providing a performance boost that rivals modern large-scale models like gpt-4o-mini and Claude Sonnet 4.5 in SimpleQA-verified performance.
By externalizing knowledge, Co-LMLM suggests a path forward where models are smaller, more efficient, and more transparent in their way of knowing what they are true facts.
Phugialy Picks

Logitech G413 SE Full-Size Mechanical Gaming Keyboard - Black | Backlit, anti-ghosting, compatible with Windows and macOS, aluminum material
Some Phugialy Picks use affiliate links. If you buy through one, Phugialy may earn a commission. It doesn't change what we recommend. Full disclosure →
Got a question about how this applies to you? →
Keep reading
Follow the thread
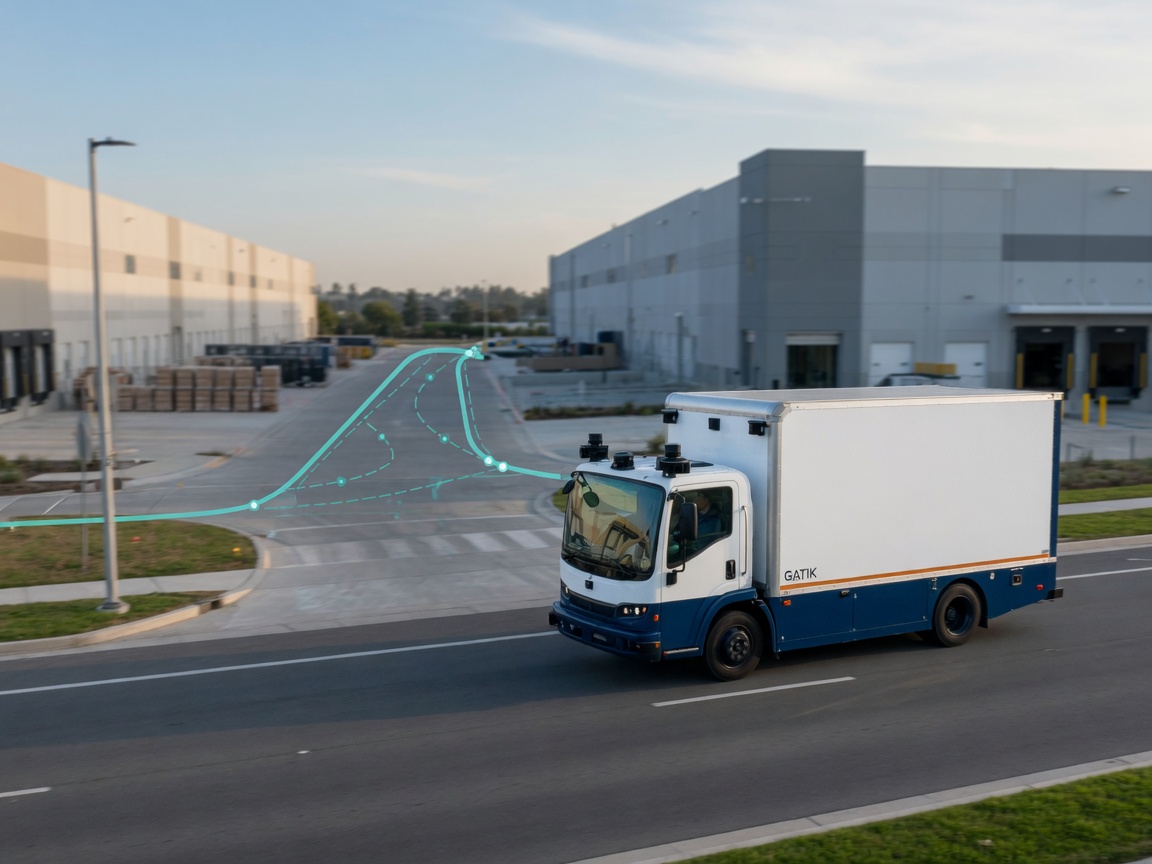
Middle-Mile Autonomy Gets Real: Inside Gatik's $200M Bet
$200 million is the headline; $600 million in contracted revenue against just $30 million recognized last year is the real story at Gatik. The company's bet on middle-mile autonomy only pays off if that pipeline converts into driverless trucks on schedule.
Read this noteSame lane, different angle
The Maintenance Debt of AI-Generated Code
We’re trading a minor speed boost for a massive, invisible tax on maintainers. Open-source projects are starting to ban AI contributions not because the code is "bad," but because the burden of auditing "code slop" is becoming unsustainable.
Jetson Orin Nano 2: Edge AI For Drones And Robots
NVIDIA's Jetson Orin Nano 2 doubles inference performance while using 40 percent less power in 15-watt mode - and it puts generative AI directly on drones and robots instead of in a data center. The specs look credible; what nobody has shown yet is independent benchmark data.